5.3.6. CMFD: Coarse Mesh Finite-Difference Acceleration
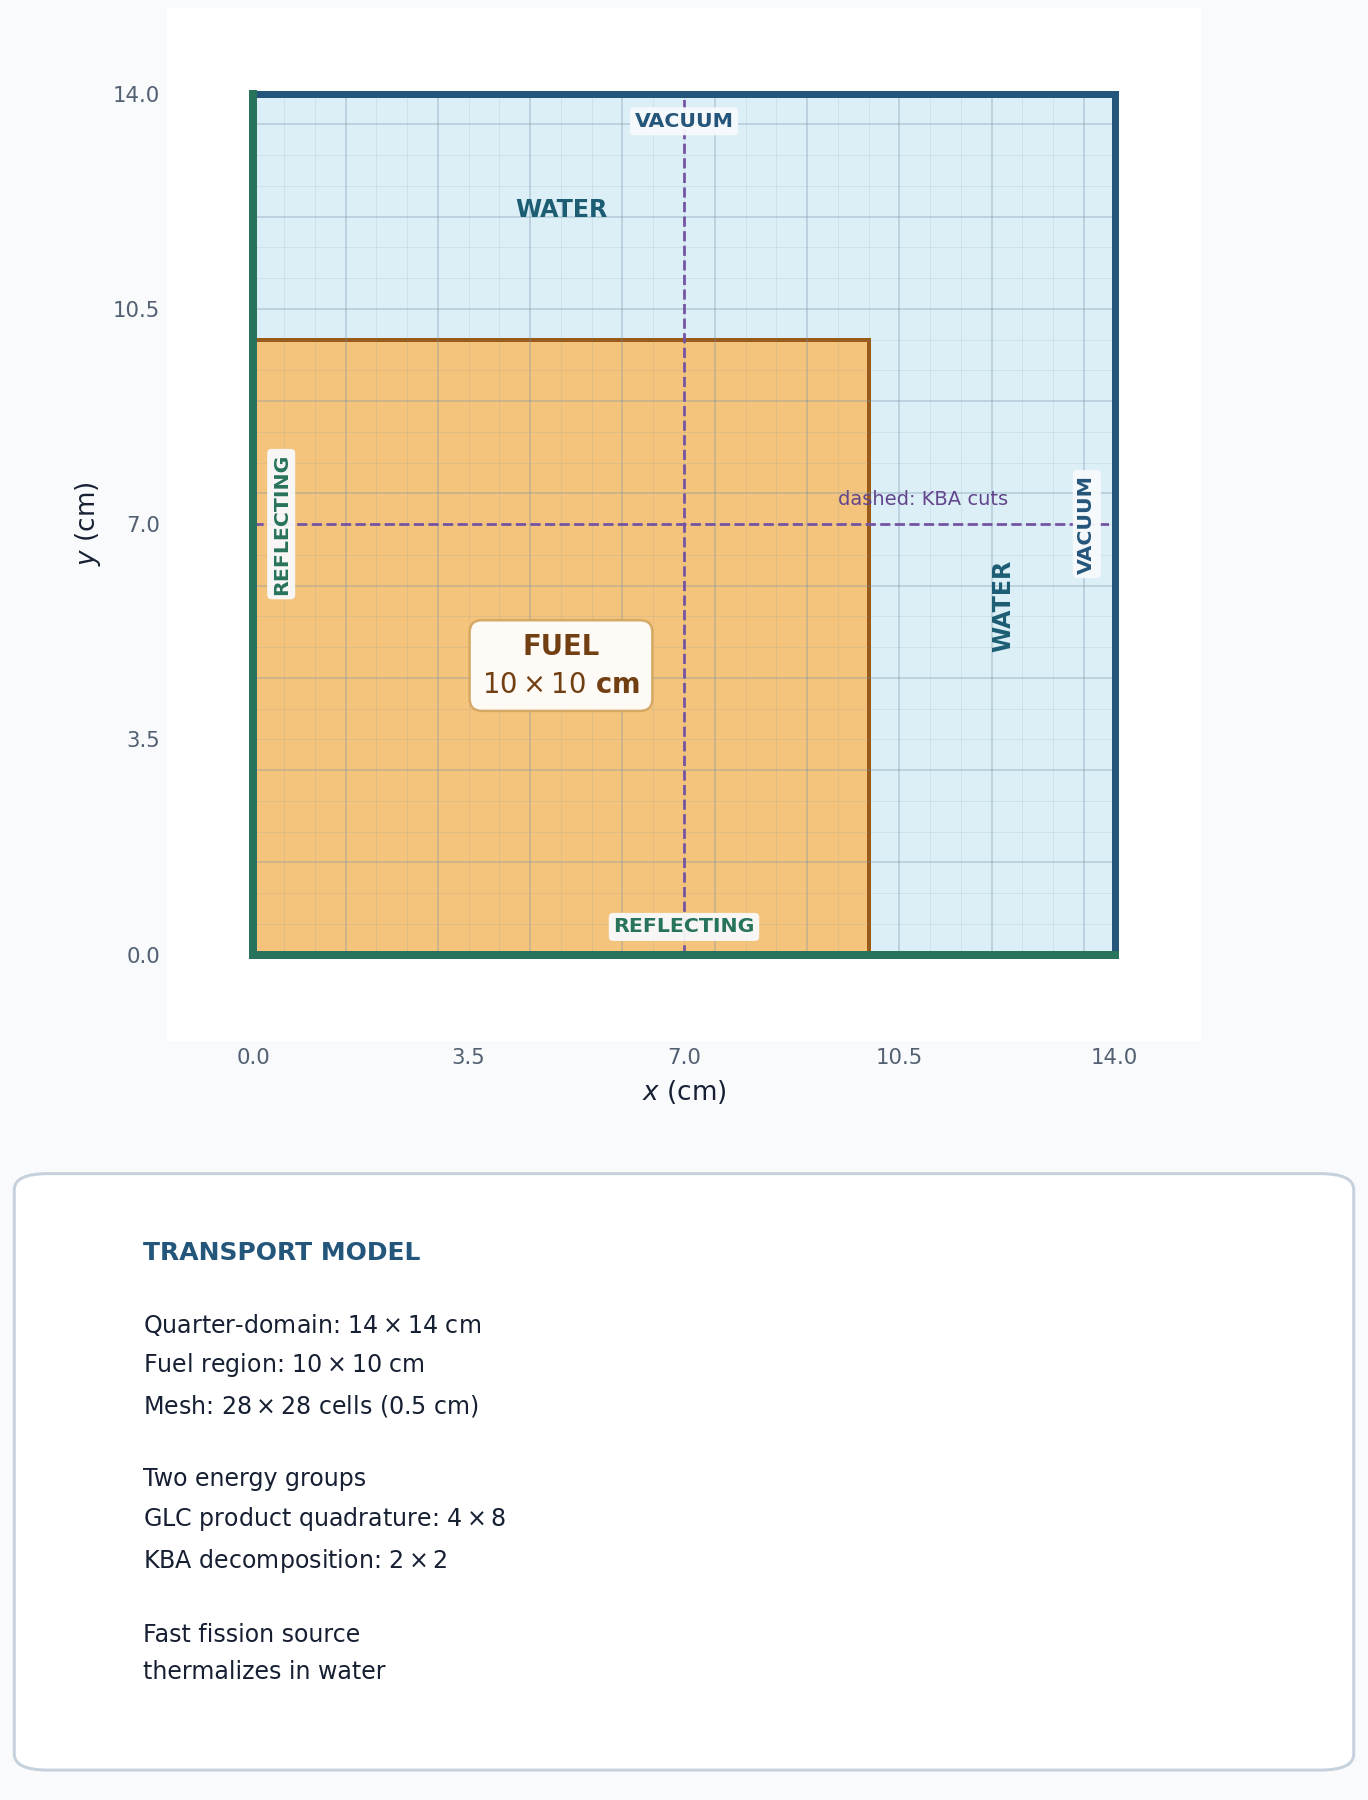
This tutorial compares unaccelerated power iteration with coarse-mesh finite-difference (CMFD) acceleration for the same two-group eigenvalue problem.
5.3.6.1. Problem setup
The 14 cm by 14 cm quarter-domain contains a 10 cm by 10 cm fuel region surrounded by water on its top and right. The left and bottom boundaries are reflecting, and the outer boundaries are vacuum. The two-group cross sections come from the OpenSn regression suite.
This weakly coupled eigenvalue iteration contains a slowly converging spatial error mode. CMFD represents that mode on an aggregated mesh and applies a low-order correction after each transport update.
[ ]:
from pathlib import Path

from mpi4py import MPI
from pyopensn.aquad import GLCProductQuadrature2DXY
from pyopensn.context import Finalize
from pyopensn.logvol import RPPLogicalVolume
from pyopensn.mesh import KBAGraphPartitioner, OrthogonalMeshGenerator
from pyopensn.solver import (
    CMFDAcceleration,
    DiscreteOrdinatesProblem,
    PowerIterationKEigenSolver,
)
from pyopensn.xs import MultiGroupXS

comm = MPI.COMM_WORLD
rank = comm.rank
tutorial_dir = Path(__file__).resolve().parent if "__file__" in globals() else Path.cwd()
repo_root = next(
    path for path in (tutorial_dir, *tutorial_dir.parents)
    if (path / "test/assets/xs").is_dir()
)
5.3.6.2. Build the transport problem
The mesh uses a 2 by 2 KBA partition, so run the generated script with four MPI processes. The transport problem, including two within-group iterations per power iteration (l_max_its=2), is identical to the one in the SCDSA tutorial, so both tutorials share the same unaccelerated baseline. Once its corrections are active, CMFD switches the groupset to one transport update per power iteration (update_wgs_max_its=1, the default). Rebuilding the problem ensures that the
baseline and accelerated calculations start from the same state.
[ ]:
def load_xs(filename):
    xs = MultiGroupXS()
    xs.LoadFromOpenSn(str(repo_root / "test/assets/xs" / filename))
    return xs


def make_problem():
    nodes = [0.5 * i for i in range(29)]
    partitioner = KBAGraphPartitioner(
        nx=2, ny=2, xcuts=[7.0], ycuts=[7.0]
    )
    mesh = OrthogonalMeshGenerator(
        node_sets=[nodes, nodes], partitioner=partitioner
    ).Execute()
    mesh.SetOrthogonalBoundaries()
    mesh.SetUniformBlockID(0)
    fuel_region = RPPLogicalVolume(
        xmin=-1.0, xmax=10.0, ymin=-1.0, ymax=10.0, infz=True
    )
    mesh.SetBlockIDFromLogicalVolume(fuel_region, 1, True)

    quadrature = GLCProductQuadrature2DXY(
        n_polar=4, n_azimuthal=8, scattering_order=1
    )
    return DiscreteOrdinatesProblem(
        mesh=mesh,
        num_groups=2,
        groupsets=[
            {
                "groups_from_to": (0, 1),
                "angular_quadrature": quadrature,
                "inner_linear_method": "petsc_richardson",
                "l_max_its": 2,
                "l_abs_tol": 1.0e-10,
            }
        ],
        xs_map=[
            {"block_ids": [0], "xs": load_xs("xs_water_g2.xs")},
            {"block_ids": [1], "xs": load_xs("xs_fuel_g2.xs")},
        ],
        boundary_conditions=[
            {"name": "xmin", "type": "reflecting"},
            {"name": "ymin", "type": "reflecting"},
            {"name": "xmax", "type": "vacuum"},
            {"name": "ymax", "type": "vacuum"},
        ],
        options={
            "save_angular_flux": True,
            "verbose_inner_iterations": False,
            "verbose_outer_iterations": False,
        },
    )
5.3.6.3. Compare power iteration and CMFD
The baseline passes no acceleration object to the eigenvalue solver. The accelerated case adds CMFDAcceleration. local_aggregation combines nearby fine cells owned by each MPI rank, while aggregation_size=4 targets about four fine cells per coarse cell. relaxation=1.0 applies the full accepted correction, and the face-current closure is left at its default, the partial-current (pCMFD) closure. Wall time is split into three phases, each the maximum across ranks: model setup (mesh,
cross sections, transport problem, and solver objects), solver initialization, and the power iterations themselves. CMFD builds its coarse-mesh data when the solve starts, so that cost falls in the power-iteration phase.
[ ]:
def solve(use_cmfd):
    comm.Barrier()
    start = MPI.Wtime()
    problem = make_problem()
    solver_options = {
        "problem": problem,
        "k_tol": 1.0e-8,
        "max_iters": 300,
    }
    if use_cmfd:
        solver_options["acceleration"] = CMFDAcceleration(
            problem=problem,
            coarse_mesh="local_aggregation",
            aggregation_size=4,
            relaxation=1.0,
            balance_residual_tolerance=1.0e-7,
        )

    solver = PowerIterationKEigenSolver(**solver_options)

    comm.Barrier()
    model_done = MPI.Wtime()
    solver.Initialize()
    comm.Barrier()
    init_done = MPI.Wtime()
    solver.Execute()
    comm.Barrier()
    end = MPI.Wtime()
    times = [
        comm.allreduce(t, op=MPI.MAX)
        for t in (model_done - start, init_done - model_done, end - init_done)
    ]
    return (
        problem,
        solver.GetEigenvalue(),
        solver.GetNumPowerIterations(),
        solver.GetNumSweeps(),
        times,
    )


_, unaccelerated_k, unaccelerated_iterations, unaccelerated_sweeps, unaccelerated_times = (
    solve(False)
)
cmfd_problem, cmfd_k, cmfd_iterations, cmfd_sweeps, cmfd_times = solve(True)
5.3.6.4. Interpret the metrics
Agreement in \(k_{\mathrm{eff}}\) checks that CMFD converges to the transport solution. Power iterations and transport sweeps measure deterministic convergence work. Wall time is shown for context and varies by machine; reporting the setup and iteration phases separately isolates the cost and benefit of CMFD itself.
[ ]:
k_difference = abs(cmfd_k - unaccelerated_k)
iteration_speedup = unaccelerated_times[2] / cmfd_times[2]
total_speedup = sum(unaccelerated_times) / sum(cmfd_times)

if rank == 0:
    print(f"Unaccelerated CMFD comparison k-effective={unaccelerated_k:.12e}")
    print(f"CMFD k-effective={cmfd_k:.12e}")
    print(f"CMFD k-effective difference={k_difference:.12e}")
    print(f"Unaccelerated CMFD comparison power iteration count={unaccelerated_iterations}")
    print(f"CMFD power iteration count={cmfd_iterations}")
    print(f"Unaccelerated CMFD comparison sweeps={unaccelerated_sweeps}")
    print(f"CMFD sweeps={cmfd_sweeps}")
    for name, times, iterations in (
        ("Unaccelerated CMFD comparison", unaccelerated_times, unaccelerated_iterations),
        ("CMFD", cmfd_times, cmfd_iterations),
    ):
        print(f"{name} model setup time (s)={times[0]:.6f}")
        print(f"{name} solver initialization time (s)={times[1]:.6f}")
        print(f"{name} power iteration time (s)={times[2]:.6f}")
        print(f"{name} total wall time (s)={sum(times):.6f}")
        print(f"{name} time per power iteration (s)={times[2] / iterations:.6f}")
    print(f"CMFD power iteration speedup={iteration_speedup:.6f}")
    print(f"CMFD total speedup={total_speedup:.6f}")

assert k_difference < 1.0e-6
assert cmfd_iterations < unaccelerated_iterations
assert cmfd_sweeps < unaccelerated_sweeps
A representative four-process run gives:
Solve |
\(k_{\mathrm{eff}}\) |
Power iterations |
Transport sweeps |
|---|---|---|---|
No acceleration |
0.59638191 |
97 |
485 |
CMFD |
0.59638194 |
31 |
31 |
The unaccelerated row is identical to the SCDSA tutorial’s baseline. The eigenvalues differ by \(3.2\times10^{-8}\), and the converged flux shapes agree to within \(10^{-6}\) of the peak. CMFD removes the slowly converging spatial mode, reducing power iterations by about 68% and transport sweeps by about 94%.
The wall-time breakdown below is the median of repeated four-process runs: five for CMFD and ten for the unaccelerated baseline, which is shared with the SCDSA tutorial:
Solve |
Model setup (s) |
Solver initialization (s) |
Power iterations (s) |
Total (s) |
Time per power iteration (ms) |
|---|---|---|---|---|---|
No acceleration |
0.015 |
<0.001 |
0.714 |
0.730 |
7.4 |
CMFD |
0.017 |
<0.001 |
0.105 |
0.122 |
3.4 |
Each CMFD power iteration costs about half as much as an unaccelerated one. The baseline performs five transport sweeps per power iteration, about 1.5 ms each, while CMFD performs one sweep followed by the coarse-mesh solve. Of the 0.105 s spent iterating, the 31 sweeps take about \(31\times1.5\) ms \(\approx0.05\) s and the coarse-mesh work, including building the coarse-mesh data, about 0.06 s. Together with the 3.1-fold reduction in power iterations, this gives a speedup of 6.8 for the power iterations.
Model setup takes about 0.015 s in both cases and solver initialization is negligible, so setup is about 2% of the unaccelerated run and 14% of the CMFD run. Including it lowers the overall speedup to 6.0. The iteration counts are deterministic; the timing values are illustrative rather than regression metrics.
5.3.6.5. Export and visualize the scalar flux
The converged eigenvalues and flux shapes agree, so the CMFD solution is used as the representative flux field. The following code exports both group scalar fluxes to VTK. It remains in Markdown so regression tests do not create output files.
from pyopensn.fieldfunc import FieldFunctionGridBased

fast_flux, thermal_flux = cmfd_problem.GetScalarFluxFieldFunction()
FieldFunctionGridBased.ExportMultipleToPVTU(
    [fast_flux, thermal_flux], "Flux/CMFD_Flux"
)
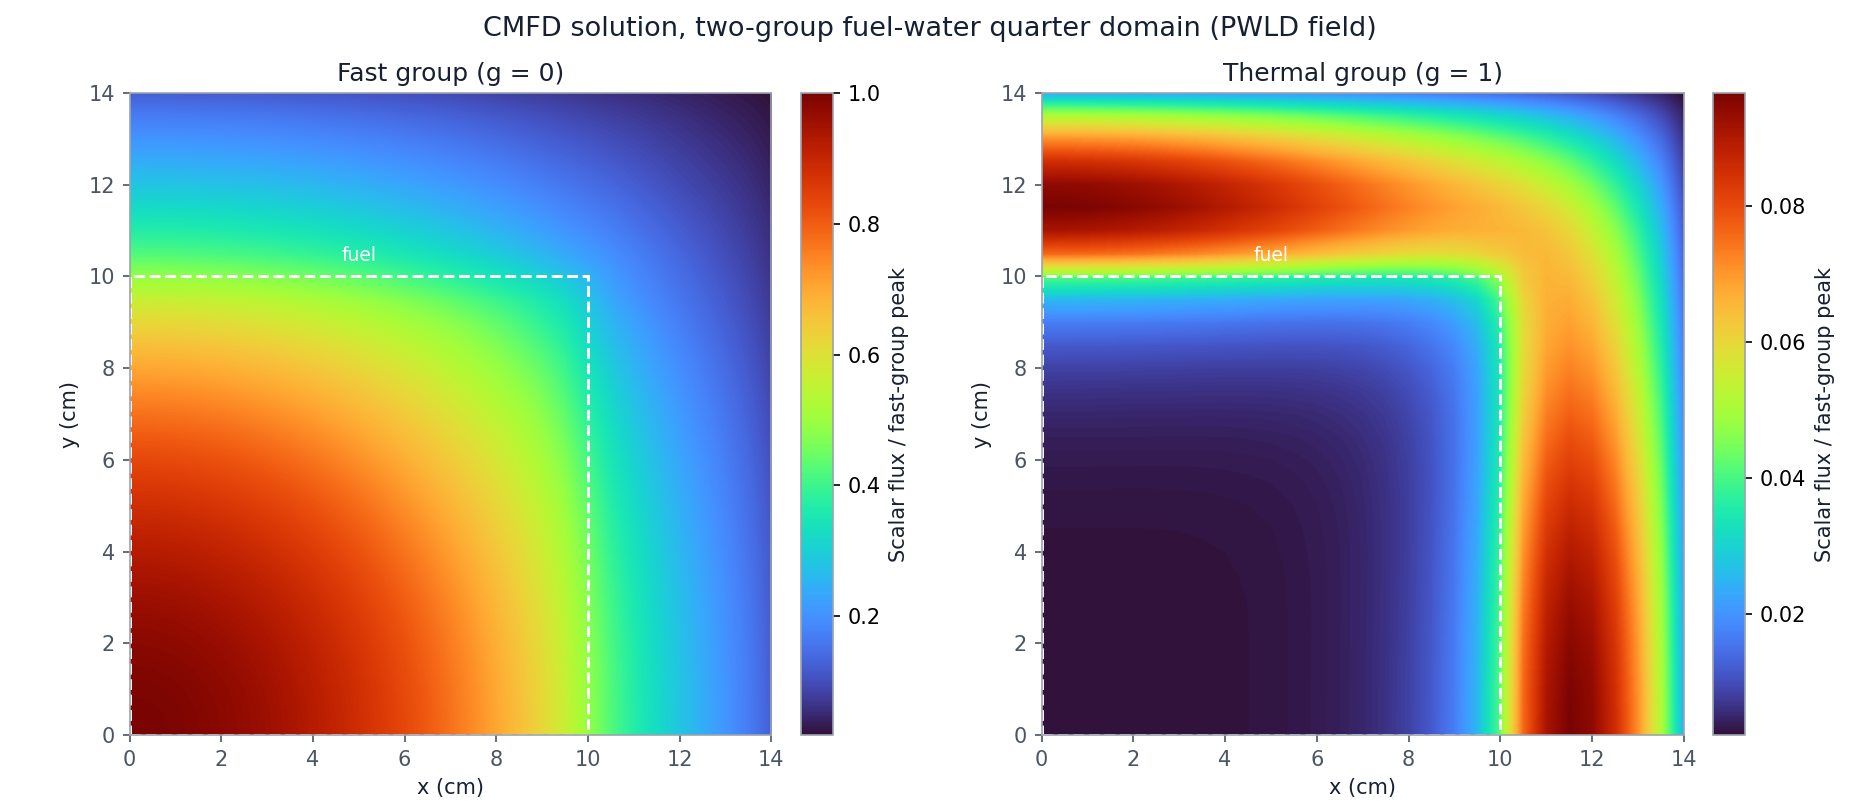
Fast-group (left) and thermal-group (right) scalar flux from the CMFD solve, both normalized to the fast-group peak. Each 0.5 cm cell is drawn with its piecewise-linear discontinuous (PWLD) solution, the bilinear field defined by the cell’s four nodal values. The dashed line marks the fuel region. Fast neutrons are born in the fuel and peak at the reflecting corner, while the thermal flux peaks in the water reflector, where fast neutrons are moderated, and is depressed inside the absorbing fuel.
5.3.6.6. Finalize (for Jupyter Notebook only)
In script mode, PyOpenSn handles finalization automatically. In a Jupyter kernel, finalize OpenSn before MPI.
[ ]:
if "opensn_console" not in globals():
    from IPython import get_ipython

    if get_ipython() is not None:
        Finalize()
        MPI.Finalize()